
Tried and tested mixes for strong pretraining. Inspired by https://huggingface.co/blog/codelion/optimal-dataset-mixing
AI & ML interests
We release large pre-training datasets to accelerate open LLM development. Part of the Hugging Face Science team (hf.co/science)
Recent Activity
View all activity
Papers

How Can We Synthesize High-Quality Pretraining Data? A Systematic Study of Prompt Design, Generator Model, and Source Data
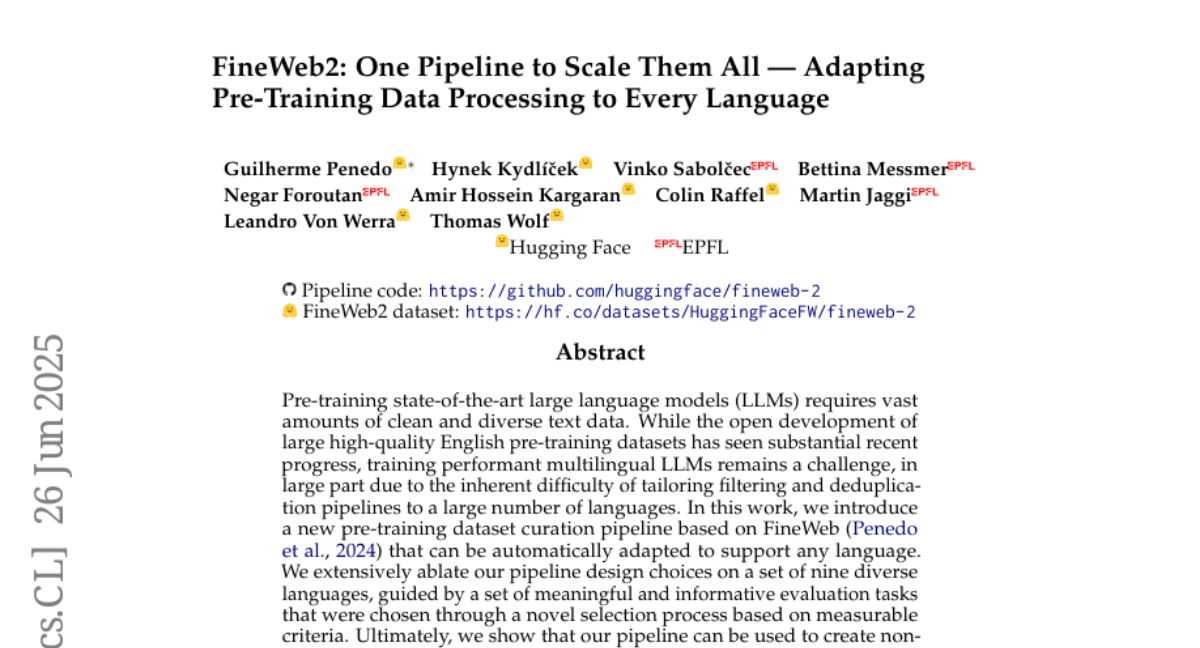
FineWeb2: One Pipeline to Scale Them All -- Adapting Pre-Training Data Processing to Every Language
-
FineWeb: decanting the web for the finest text data at scale
🍷1.46kExplore the FineWeb dataset and its creation process
-
HuggingFaceFW/fineweb
Viewer • Updated • 52.5B • 362k • 3.71k -
HuggingFaceFW/fineweb-edu
Viewer • Updated • 3.5B • 435k • 1.38k -
HuggingFaceFW/fineweb-edu-score-2
Viewer • Updated • 13.9B • 19.4k • 90
1.8B models trained on 350BT to compare different pretraining datasets
-
HuggingFaceFW/ablation-model-fineweb-edu
Text Generation • 2B • Updated • 797 • 24 -
HuggingFaceFW/ablation-model-fineweb-v1
Text Generation • 2B • Updated • 167 • 14 -
HuggingFaceFW/ablation-model-refinedweb
Text Generation • 2B • Updated • 62 • 3 -
HuggingFaceFW/ablation-model-c4
Text Generation • 2B • Updated • 61 • 4
-
FineWeb2: One Pipeline to Scale Them All -- Adapting Pre-Training Data Processing to Every Language
Paper • 2506.20920 • Published • 81 -
HuggingFaceFW/fineweb-2
Viewer • Updated • 4.48B • 128k • 918 -
Scaling FineWeb to 1000+ languages: Step 1: finding signal in 100s of evaluation tasks
📝96Evaluate multilingual models using FineTasks
FineWeb-Edu datasets, classifier and ablation model
-
HuggingFaceFW/fineweb-edu
Viewer • Updated • 3.5B • 435k • 1.38k -
HuggingFaceFW/fineweb-edu-score-2
Viewer • Updated • 13.9B • 19.4k • 90 -
HuggingFaceFW/fineweb-edu-classifier
Text Classification • 0.1B • Updated • 34.9k • • 229 -
HuggingFaceFW/ablation-model-fineweb-edu
Text Generation • 2B • Updated • 797 • 24
Ablation models trained for our data experiments.
-
HuggingFaceFW/ablation-exp-textext-warc_trafilatura-28BT
Text Generation • 2B • Updated • 14 • 1 -
HuggingFaceFW/ablation-exp-textext-wet-28BT
Text Generation • 2B • Updated • 9 -
HuggingFaceFW/ablation-exp-fw-base_filtering-350BT
Text Generation • 2B • Updated • 13 -
HuggingFaceFW/ablation-exp-dedup-global_minhash-350BT
Text Generation • 2B • Updated • 12
Tried and tested mixes for strong pretraining. Inspired by https://huggingface.co/blog/codelion/optimal-dataset-mixing
-
FineWeb2: One Pipeline to Scale Them All -- Adapting Pre-Training Data Processing to Every Language
Paper • 2506.20920 • Published • 81 -
HuggingFaceFW/fineweb-2
Viewer • Updated • 4.48B • 128k • 918 -
Scaling FineWeb to 1000+ languages: Step 1: finding signal in 100s of evaluation tasks
📝96Evaluate multilingual models using FineTasks
-
FineWeb: decanting the web for the finest text data at scale
🍷1.46kExplore the FineWeb dataset and its creation process
-
HuggingFaceFW/fineweb
Viewer • Updated • 52.5B • 362k • 3.71k -
HuggingFaceFW/fineweb-edu
Viewer • Updated • 3.5B • 435k • 1.38k -
HuggingFaceFW/fineweb-edu-score-2
Viewer • Updated • 13.9B • 19.4k • 90
FineWeb-Edu datasets, classifier and ablation model
-
HuggingFaceFW/fineweb-edu
Viewer • Updated • 3.5B • 435k • 1.38k -
HuggingFaceFW/fineweb-edu-score-2
Viewer • Updated • 13.9B • 19.4k • 90 -
HuggingFaceFW/fineweb-edu-classifier
Text Classification • 0.1B • Updated • 34.9k • • 229 -
HuggingFaceFW/ablation-model-fineweb-edu
Text Generation • 2B • Updated • 797 • 24
1.8B models trained on 350BT to compare different pretraining datasets
-
HuggingFaceFW/ablation-model-fineweb-edu
Text Generation • 2B • Updated • 797 • 24 -
HuggingFaceFW/ablation-model-fineweb-v1
Text Generation • 2B • Updated • 167 • 14 -
HuggingFaceFW/ablation-model-refinedweb
Text Generation • 2B • Updated • 62 • 3 -
HuggingFaceFW/ablation-model-c4
Text Generation • 2B • Updated • 61 • 4
Ablation models trained for our data experiments.
-
HuggingFaceFW/ablation-exp-textext-warc_trafilatura-28BT
Text Generation • 2B • Updated • 14 • 1 -
HuggingFaceFW/ablation-exp-textext-wet-28BT
Text Generation • 2B • Updated • 9 -
HuggingFaceFW/ablation-exp-fw-base_filtering-350BT
Text Generation • 2B • Updated • 13 -
HuggingFaceFW/ablation-exp-dedup-global_minhash-350BT
Text Generation • 2B • Updated • 12